Inside a Modern Language Model: Data, Scale and Architecture
How a frontier language model is built before any chat training: the web data, the scaling rules, the layer design, experts, and the machines that train it.
In 2024, Meta trained a language model with 405 billion parameters on 15.6 trillion tokens of text. The run used up to 16,384 GPUs. In one 54-day stretch of it, the job stopped 466 times, most often because a piece of hardware failed. Each time, the system loaded the last saved copy of the model and carried on.
At the end there was a file of numbers that could continue almost any text. No chat training had happened yet. That file is the base model, and it is the subject of this part. What goes into it? How big should it be? What does each layer look like inside, and what does it cost to make?
This is Part 5 of How AI Got Here. Part 1 told the story of neural networks up to the Transformer and the first scaling laws. Part 2 covered classical machine learning, and Part 3 covered reinforcement learning. Part 4 showed how a base model becomes an assistant. This part goes back one step and opens the base model itself, as it is built in October 2026.
The core of the 2017 design is still there. Most changes after 2020 make the same model cheaper to train, cheaper to serve, or able to read longer inputs.
Part 1 introduced the next-token loss. The model reads a text, and at every position it gives a probability to each possible next token. The loss is the negative log of the probability it gave to the token that really came next. Averaged over trillions of positions, that one number is the whole goal of pre-training.
The loss is hard to feel, so people often turn it into perplexity. Think of a quiz where the model must guess the next word. A perplexity of 7 means the model is as unsure as if it had to pick fairly between 7 equal choices at every step.
PPL=exp(−T1t=1∑Tlogpθ(xt∣x<t))=eL
T is the number of tokens, xt is the token at position t and x<t are the tokens before it. pθ is the model with parameters θ. The part inside the brackets is the average loss L, so perplexity is just e to the power of the loss.
Our script gives the scale. A new model that guesses at random over a vocabulary of 128,000 tokens has a loss of ln128,000=11.76 and a perplexity of 128,000. A loss of 4.0 is a perplexity of 54.60, and a loss of 2.0 is 7.39. A single token with probability 0.9 costs 0.105; one with probability 0.01 costs 4.605.
A FLOP is one floating-point operation, such as one multiply or one add. Training cost is counted in FLOPs, and there is a famous shortcut for it.
C≈6ND
C is the total training compute in FLOPs, N is the number of parameters and D is the number of training tokens. Each parameter takes part in one multiply and one add for each token on the forward pass, which is 2 FLOPs. The backward pass costs about twice the forward pass, which adds 4. So every parameter costs about 6 FLOPs per token.
A model with 1 billion parameters trained on 20 billion tokens costs 6×109×2×1010=1.2×10²⁰ FLOPs. The rule leaves out the attention scores, which matter only for long texts. Jared Kaplan and colleagues used it in their 2020 paper, and almost every lab uses it today.
Here are some real runs, from our script:
Model
Parameters N
Tokens D
6ND (FLOPs)
Tokens per parameter
GPT-3 (2020)
175B
300B
3.15×10²³
1.7
Gopher (2021)
280B
300B
5.04×10²³
1.1
Chinchilla (2022)
70B
1.4T
5.88×10²³
20
Llama 3 8B (2024)
8B
15T
7.2×10²³
1,875
Llama 3 405B (2024)
405B
15.6T
3.79×1025
38.5
DeepSeek-V3 (2024)
37B active
14.8T
3.29×1024
400
The Llama 3 paper itself reports 3.8×1025 FLOPs for the 405B model, so the shortcut agrees. For DeepSeek-V3, N is the number of parameters each token uses, not the total; the section on experts explains why.
Part 1 introduced the first scaling-law paper. Its main picture shows why it changed how labs plan.
Kaplan's team also asked how to split a growing budget. Their answer was to put most of it into parameters: the best model size grew as N∝C0.73. GPT-3, Gopher and Megatron-Turing NLG followed that advice. They were very large and trained on 300 billion tokens or fewer.
In March 2022, Jordan Hoffmann and colleagues at DeepMind repeated the study with a different method. They trained over 400 models, and changed the learning-rate schedule to match each run's length, which Kaplan's runs had not done.
The paper fits one formula to all its runs. It splits the loss into three parts. One is a floor that no model can beat, one falls as the model grows, and one falls as the data grows.
L(N,D)=E+NαA+DβB
E is the irreducible loss, the randomness of language itself; no model can predict a coin toss in a story. A/Nα is the penalty for a finite model and B/Dβ the penalty for finite data. α and β say how fast each penalty shrinks. The fitted values in the paper are E=1.69, A=406.4, B=410.7, α=0.34 and β=0.28.
Put in Gopher, with N=280×109 and D=300×109. The model term is 0.0521 and the data term is 0.2511, for a loss of 1.9933. Gopher's loss was mostly a data problem. For Chinchilla, with N=70×109 and D=1.4×10¹², the terms are 0.0835 and 0.1632, for a loss of 1.9366. The smaller model wins because its two penalties are better balanced.
To find the best split for a budget, put D=C/(6N) into the formula and find the N with the lowest loss. Each budget gives a U-shaped curve. Too small a model wastes the budget on tokens it cannot use; too large a model sees too few tokens.
Drawn from the paper's fitted formula L(N, D) = 1.69 + 406.4/N^0.34 + 410.7/D^0.28, not from its measured runs. Too small a model starves on parameters; too large a model starves on tokens.
Calculus gives the bottom of each U in closed form:
With the fitted values, the exponent is 0.452 for N and 0.548 for D. So as the budget grows, the best model grows a little slower than its data, and the two grow at almost the same rate. That is the paper's main finding, and it is very different from Kaplan's 0.73.
Chinchilla answers one question: the lowest loss for a training budget. But a model is trained once and then used millions of times. Every user's token costs about 2N FLOPs to produce, so a smaller model is cheaper forever. If you expect heavy use, you should train a smaller model for longer than "optimal".
Our script puts numbers on that trade, with the Chinchilla fit as a rough guide (Meta's data and tokenizer differ). An 8B model on 15T tokens uses 7.2×10²³ FLOPs and reaches a fitted loss of 1.9485. The compute-optimal model for the same budget has 35.6B parameters and a loss of 1.9226. The small model gives up only 0.0259 of loss, and it is 4.5 times cheaper per token to serve. The same 8B model with 20 tokens per parameter would reach only 2.1640.
If models keep growing, and small ones keep reading more, the data must grow too. Epoch AI estimated in 2024 that the stock of good public human text is on the order of 300 trillion tokens. Their paper's figure is 320 trillion, with a wide range. They expect frontier runs to reach that size "between 2026 and 2032", and sooner if models are over-trained.
Llama 3 405B already read 15.6 trillion tokens, so the wall is not far off for text alone. That is one reason why labs now mix in images, audio and video, and why they write data with models. It is also why the second axis in Part 4, test-time compute, matters so much. A model that thinks longer can get better without any new pre-training data.
A crawl is raw HTML: menus, cookie banners, adverts, spam, copies of copies, and pages in hundreds of languages. Maybe a small share is text you would want a model to learn from. The art of pre-training data is throwing away the rest without throwing away the good.
Each step throws data away. Deduplication and the quality classifier (highlighted) changed results the most in the open studies of 2023 and 2024.
The first steps are mechanical. Text is pulled out of the HTML, and a small classifier guesses the language of each page. Simple rules then drop pages that are too short, too repetitive or full of bad words. C4, the "Colossal Clean Crawled Corpus" that Google built for its T5 model in 2019, used rules such as "keep only lines that end with a punctuation mark".
The web repeats itself. The same news story, licence text or product page appears thousands of times. A model trained on such copies memorises them and wastes compute on them. So every pipeline removes near-duplicates.
Near copies are measured by overlap. Cut each document into shingles, runs of a few words in a row, and compare the two sets:
J(A,B)=∣A∪B∣∣A∩B∣
A and B are the sets of shingles of two documents. ∣A∩B∣ counts the shingles they share, and ∣A∪B∣ counts all distinct shingles of both. J is the Jaccard similarity: 1 for identical sets, 0 for no overlap.
Take "the cat sat on the mat and looked out of the window" and the same sentence ending in "door". With 3-word shingles, each has 10. They share 9, and the union has 11, so J=9/11=0.8182. They are near duplicates.
Comparing every pair of billions of pages is impossible. MinHash gives each document a short signature of hash values, so that two signatures agree at one spot with probability J. FineWeb uses 112 hashes in 14 buckets of 8. Two documents are flagged if all 8 hashes agree in any one bucket. The chance of that is 1−(1−J8)14. From our script, it is 0.0533 at J=0.5, 0.7716 at 0.75 and 0.9996 at 0.9: a soft threshold near 75%.
One of its results surprised the authors. They first deduplicated across all 96 snapshots at once, as you might expect to do.
Rules can remove obvious junk. They cannot tell a clear explanation from a dull one. For that, labs train a quality classifier: a small model that scores each page, so the pipeline keeps the best ones.
For FineWeb-Edu, Llama-3-70B-Instruct scored 460,000 web pages from 0 to 5 for educational value. A small classifier learned those scores and ran over all 15 trillion tokens, which took 6,000 H100 GPU hours. Pages that scored 3 or more were kept: 1.3 trillion tokens. A model trained on them matched the final MMLU score of another open set, Matrix, with almost ten times fewer tokens.
DataComp-LM (DCLM), from a large team of university and industry researchers in June 2024, ran the same kind of test as a contest. It released a pool of 240 trillion tokens from Common Crawl and fixed the training code, so only the data changed. Its best filter, also a small classifier, trained a 7B model to 64% on MMLU with 2.6 trillion tokens. Llama 3's paper describes classifiers of the same kind, trained on Llama 2's judgements.
Code and maths pages are rare on the web, but they teach skills that help with reasoning in general. Pipelines use separate classifiers to find them. Llama 3's final mix had about 50% general knowledge, 25% maths and reasoning, 17% code and 8% text in other languages.
In June 2023, Microsoft's phi-1 paper, "Textbooks Are All You Need", made the case in its title. Its model had only 1.3 billion parameters. It was trained on 6 billion tokens of "textbook quality" web data and 1 billion tokens of textbooks and exercises written by GPT-3.5. It reached 50.6% on the HumanEval coding test, far above much larger models of the time. By 2025, rewriting web text with a model was a standard step, for example in the Kimi K2 report.
Choosing the mix is itself an experiment. Llama 3 trained small models on candidate mixes, fitted scaling laws to them, and predicted how a large model would do. The end of training gets special care too, because the model learns most from what it reads last, while its learning rate falls.
Llama 3's paper says that "during pre-training on the final 40M tokens, we linearly annealed the learning rate to 0". During that phase, the mix was changed "to upsample data sources of very high quality". The final model is an average of several checkpoints from the annealing phase. Meta also used annealing as a test: train briefly on a new small data set while the rate falls, and see if scores rise.
This end phase has grown into a stage of its own, often called mid-training. As Part 4 described, Olmo 3 runs 100 billion tokens of maths, code and question answering after its main pre-training. Long-context training usually follows.
A model reads integers, not letters. A tokenizer turns text into a list of token IDs from a fixed vocabulary. Whole words would make the vocabulary endless, and single letters would make texts very long. The standard answer sits between them, and it came from data compression.
Rico Sennrich, Barry Haddow and Alexandra Birch brought BPE to neural translation in 2016, and printed the whole algorithm in their paper.
We ran the same toy example. The first merge is "e" + "s", with a count of 9 (6 from newest, 3 from widest). Then "es" + "t", then "est" + "", all with 9. Then "l" + "o" and "lo" + "w", with 7. After 10 merges, the word "lowest", which was never in the data, splits into "low" and "est".
The toy vocabulary of Sennrich, Haddow and Birch (2016), run by our script with the paper's own algorithm. Real vocabularies, built on bytes instead of letters, hold 32,000 to 262,000 tokens.
GPT-2 in 2019 ran BPE on bytes, not letters, so any text, in any script, can be encoded. Its vocabulary had 50,257 tokens. Llama 2 in 2023 used 32,000. Since then, vocabularies have grown: Llama 3 has 128,000 tokens (100,000 from OpenAI's tiktoken plus 28,000 for other languages). DeepSeek-V3 has 128,000, and Gemma 3 uses Gemini 2.0's tokenizer with 262,000 entries.
A bigger vocabulary means fewer tokens per text, so the model reads more text for the same compute. Meta reports that its new tokenizer raised the average from 3.17 to 3.94 English characters per token, compared with Llama 2's. The cost is a bigger embedding table and output layer, and rare tokens that the model sees too seldom to learn well. Languages that were poorly served by older tokenizers, where one word could cost five or more tokens, gain the most.
The Transformer of 2017 had an encoder and a decoder for translation. Almost every large language model since GPT has kept only the decoder: a stack of identical layers, each with attention and a feed-forward network. The layer of 2026 looks like the old one from far away. Up close, almost every part has been swapped.
Same skeleton, new parts. The norm moved before each block, the positions moved into attention, the keys and values are shared, and the feed-forward got a gate and often a router.
Deep networks need their numbers kept at a steady size from layer to layer, or training blows up or stalls. Normalisation does this. The 2017 Transformer normalised after adding each block's output to its input ("post-norm"). GPT-2 moved the normalisation to the input of each block ("pre-norm"). In 2020, Ruibin Xiong and colleagues showed why that helps. With pre-norm, the gradients are well behaved at the start, so training needs less of a careful warm-up.
In 2019, Biao Zhang and Rico Sennrich proposed a cheaper normaliser. LayerNorm subtracts the mean and divides by the standard deviation. RMSNorm skips the mean and divides by the root mean square.
RMSNorm(x)i=d1∑j=1dxj2+ϵxigi
x is the vector for one token, with d numbers. The square root is the root mean square: square every number, take the average, take the root. ϵ (epsilon) is a tiny number that prevents division by zero, and gi is a learned scale for each position.
Take x=[1,2,3,4], with g=1. The mean of the squares is (1+4+9+16)/4=7.5, and its root is 2.7386. RMSNorm gives [0.3651,0.7303,1.0954,1.4606]. LayerNorm would first subtract the mean 2.5 and give [−1.3416,−0.4472,0.4472,1.3416]. RMSNorm keeps the direction of the vector and only fixes its size. The paper reports the same quality as LayerNorm and running times 7% to 64% shorter.
The feed-forward network is where most of a dense model's parameters live. In 2017 it was two matrices with a ReLU between them. In 2020, Noam Shazeer tested a family of gated versions, and one, SwiGLU, became the standard.
FFNSwiGLU(x)=(SiLU(xW)⊙xV)W2,SiLU(z)=1+e−zz
x is a token's vector. W and V are two matrices that widen it to dff numbers, and W2 brings it back to d. ⊙ means multiply element by element. SiLU (also called Swish) is a smooth version of ReLU. It is close to z for large z and close to 0 for very negative z.
Take one element with xW=2 and xV=3. SiLU(2) is 1.7616, so the output is 1.7616×3=5.2848. If xV were 0, the output would be 0 whatever the gate said. The two paths learn together which features to pass on.
SwiGLU has three matrices instead of two. To keep the parameter count the same, dff is set near 38d instead of 4d, since 3×d×38d=8d2 is what two matrices of d×4d cost. Llama 3 8B uses d=4,096 and dff=14,336, which is 3.5 times wider. Its feed-forward weights alone come to 176,160,768 per layer.
Attention, on its own, sees a set of tokens with no order. The 2017 Transformer added a fixed wave pattern to each token's vector at the input. That works, but the model must learn to pull position out of the mixture again, and it handles texts longer than its training texts poorly.
In 2021, Jianlin Su and colleagues at Zhuiyi Technology proposed rotating the queries and keys instead. Think of a clock hand. A token at position m has its hand turned by m steps. Two hands turned by 3 and 1 steps make the same angle as two hands turned by 7 and 5 steps. Attention compares angles, so it sees only the distance.
For one pair of numbers, the rotation is a 2-by-2 matrix:
q and k are a pair of numbers from a query and a key. m and n are the positions of their tokens, and θ (theta) is the turning speed for this pair. The right side shows that the score depends on m and n only through n−m. That works because turning one vector by a and another by b changes the angle between them by b−a.
Our script checks it with q=(1,0.5), k=(0.8,−0.2) and θ=0.3. Without rotation, q⋅k=0.7. With the query at position 3 and the key at 1, the score is 0.2389. At positions 7 and 5 it is 0.2389, and at 102 and 100 it is again 0.2389. At positions 5 and 1, four apart, it is −0.3056.
A real head has 64 such pairs, each turning at its own speed, from one radian per token down to a full turn every 54,000 tokens (base 10,000) or 2.6 million tokens (base 500,000).
A real head has many pairs, each with its own speed: θi=b−2i/d for pair i of a head with d numbers, with a baseb. Fast pairs track nearby words; slow pairs track far ones. With d=128 and the usual base of 10,000, the slowest pair turns once every 54,410 tokens. Llama 3 raised the base to 500,000, which makes the slowest turn last 2,559,196 tokens and helps with long texts.
Attention compares every token with every other token. For n tokens, that is a table of n×n scores per head and per layer.
FLOPsscores≈2n2dper layer,memoryscores=n2 numbers per head
n is the sequence length and d the model width. Our script shows the memory side for one head in 16-bit numbers. At 2,048 tokens the score table is 8 MiB. At 8,192 it is 128 MiB. At 131,072 tokens it is 32,768 MiB, or 32 GiB, for a single head of a single layer.
Most of the time of plain attention goes not into arithmetic but into writing the big score table to HBM and reading it back. In May 2022, Tri Dao and colleagues at Stanford fixed that without changing the result.
The paper reports a 3× speedup on GPT-2 training at 1K tokens. FlashAttention-2 and -3 followed for newer GPUs, and some version of it now runs inside nearly every training and serving system. The arithmetic is still n2, which is why long-context models also use the sparser patterns of the attention series, such as Gemma 3's local layers.
When a model writes text, it keeps the keys and values of every earlier token, so it does not compute them again. This store is the KV cache, and the inference series covers it in depth. Its size often decides how many users one GPU can serve.
KV bytes per token=2×L×Hkv×dh×b
The 2 counts keys and values. L is the number of layers and Hkv the number of key-value heads. dh is the size of each head and b the bytes per number (2 for 16-bit). Plain multi-head attention (MHA) has one key-value head per query head.
Take the shape of Llama 3 70B: 80 layers, 64 query heads of size 128. With MHA, one token would need 2×80×64×128×2=2,621,440 bytes, or 2,560 KiB. A 128K-token chat would need 320 GiB, four times an 80 GB GPU. That is why nobody builds it that way.
Noam Shazeer proposed MQA in 2019. It shrinks the cache by the number of heads, but it can lose quality. In 2023, Joshua Ainslie and colleagues at Google proposed GQA as the middle way. They also showed that an existing MHA model can be converted with about 5% of its original training compute. Llama 3 70B uses 8 key-value heads for its 64 query heads: 320 KiB per token, and 40 GiB for 128K tokens. MQA, with one head, would need 40 KiB.
DeepSeek went further in May 2024 with multi-head latent attention in DeepSeek-V2.
DeepSeek-V3 stores 512 numbers for the latent plus 64 for a small RoPE key, per layer. With 61 layers, that is 61×576×2=70,272 bytes, or 68.6 KiB per token. The same shape with full MHA, 128 heads of size 128, would need 3,904 KiB. MLA is 56.9 times smaller.
Bytes per token = 2 (keys and values) × layers × KV heads × head size × 2 bytes. The MHA rows are what the same shapes would need without sharing. Numbers from our script.
A model trained on 8,000-token texts does not simply work on 128,000. Its slow RoPE pairs never turned that far, so long distances look like nothing it has seen. The fixes stretch the rotations.
In 2023, Shouyuan Chen and colleagues at Meta proposed position interpolation. It divides every position by a scale s, so 128K positions fit into the old 8K range. From 8K to 128K, s=16. Later methods scale different pairs by different amounts, so fast pairs keep their precision. YaRN, from Bowen Peng and colleagues in 2023, needed "10x less tokens and 2.5x less training steps than previous methods".
Labs now do this as a stage of pre-training. Llama 3 went from 8K to 128K "in six stages". DeepSeek-V3 used YaRN to go from 4K to 32K and then to 128K. In February 2024, Google's Gemini 1.5 report showed "near-perfect retrieval (>99%) up to at least 10M tokens" in research tests. The models it shipped took one or two million tokens. Google has not published how it does this.
A dense model uses every weight for every token. That ties two things together: what the model can know (its parameters) and what each token costs (its compute). A mixture of experts cuts that tie. The feed-forward block is replaced by many smaller blocks, the experts, and a small network chooses a few of them for each token.
Think of a hospital. It has many specialists, but each patient sees only two or three, chosen at the front desk. The hospital knows a great deal, and each visit stays short. The front desk is the router, and it learns its choices during training.
x is a token's vector and Wr the router's weight matrix, with one column per expert. p holds one probability per expert. TopK(p) is the set of the k experts with the highest probabilities. Ei(x) is the output of expert i, and the fraction is its gate: its probability, rescaled so the chosen gates add up to 1.
Take 8 experts and a token whose router scores are 2.0, 1.0, 0.5, 0.1, −0.3, −1.0, 0.0 and 0.3. Softmax turns them into 0.4528, 0.1666, 0.1010, 0.0677, 0.0454, 0.0225, 0.0613 and 0.0827. With k=2, experts 0 and 1 win. Their gates are 0.4528/0.6194=0.7311 and 0.2689. The other six experts do no work for this token.
One token of our script's router. Mixtral uses exactly this shape: 8 experts, top 2. DeepSeek-V3 picks 8 of 256 routed experts, plus 1 shared expert that every token uses.
Noam Shazeer and colleagues at Google made this work for language models in 2017, with a paper titled "Outrageously Large Neural Networks". It used thousands of experts between LSTM layers. The idea moved into Transformers with Google's GShard in 2020, then into the Switch Transformer.
A router left alone tends to collapse. A few experts get slightly better early, so the router sends them more tokens, so they get better still. The others starve. And in practice each expert lives on a different GPU, so an overloaded expert makes the others wait.
To keep the load even, Switch adds a small load-balancing loss to the training loss:
Laux=αNi=1∑NfiPi
N is the number of experts. fi is the share of tokens in the batch that were actually sent to expert i. Pi is the average router probability for expert i over the batch. α is a small weight; the paper uses 10−2. The sum is smallest when both shares are spread evenly.
With 8 experts and perfect balance, every fi and Pi is 1/8, so N∑fiPi=8×8×641=1. If every token goes to expert 0 with probability 1, the sum is 8, the worst case. Our script also ran a random router that favours two experts, on 4,096 tokens. It sent 46.8% and 24.8% of tokens to them, and scored 1.7124, so the loss pushes it back toward 1.
In December 2023, Mistral AI released Mixtral 8x7B with open weights, and its paper followed in January 2024.
DeepSeek-V3: many small experts and one shared one#
DeepSeek pushed the design in a different direction: many small experts instead of a few large ones, plus experts that every token uses.
DeepSeek-V3 has 61 layers. All but the first three use MoE, with 1 shared expert and 256 routed experts, of which each token uses 8. So each token passes through 9 of 257 expert networks. The model has 671 billion parameters, and 37 billion, 5.5%, are active for each token.
It also changed how balance is kept. A large auxiliary loss can hurt quality. So DeepSeek-V3 gives each expert a bias, which is added to its score only when the top 8 are chosen. After each step, the bias of an overloaded expert goes down and that of an idle one goes up. The report calls this "auxiliary-loss-free" balancing, and keeps only a tiny loss of the Switch kind as a backstop.
Google has said the most. The Gemini 1.5 report of 2024 calls Gemini 1.5 Pro "a sparse mixture-of-expert (MoE) Transformer-based model". The 2025 report on Gemini 2.5 says the same of the whole family, and adds what it is for.
The Gemini 3 Pro model card says the same: a "sparse mixture-of-experts (MoE)" Transformer "with native multimodal support for text, vision, and audio inputs", trained on Google's TPUs. Meta's Llama 4 models of April 2025 are MoE too. Llama 4 Scout has 17 billion active parameters, 16 experts and 109 billion in total; Maverick has 17 billion active, 128 experts and 400 billion in total. Kimi K2 has about a trillion parameters with 32 billion active.
OpenAI and Anthropic do not publish the architecture of their frontier models. Press reports about their sizes and designs exist, but none comes from the labs, so this part does not repeat them.
Part 1 showed the Vision Transformer of 2020, which treats an image as a sequence of patches. That one idea is what lets a language model see.
Early open models used late fusion: a frozen image encoder, a small adapter and a language model, trained together only at the end. Google's first Gemini report, in December 2023, described its models as multimodal from the start of training. Meta's Chameleon paper of May 2024 described "early-fusion token-based mixed-modal models", and Llama 4 uses "early fusion to seamlessly integrate text and vision tokens".
A 224 × 224 image with 16 × 16 patches gives 196 tokens, the setting of the 2020 Vision Transformer. Modern models use bigger images and compress the patch tokens.
Audio and video follow the same pattern. Sound is cut into short frames, an encoder turns them into vectors, and video is a stream of image patches plus its sound track. The Gemini 1.5 report tested retrieval on up to 9.7 million audio tokens. The exact encoders inside Gemini and other closed models are not public.
Training a frontier model needs thousands of accelerators working as one. Two families dominate: NVIDIA's GPUs and Google's TPUs.
An NVIDIA H100 does 989.4 trillion 16-bit FLOPs per second at its peak, on dense matrices. It carries 80 GB of HBM3 memory at 3.35 TB/s. Meta trained Llama 3 405B on up to 16,384 of them.
Google builds its own chips and joins them into pods. Gemini 1.5 was trained on several 4,096-chip pods of TPU v4, the report says. A TPU v5p chip does 459 trillion 16-bit FLOPs per second, and one pod holds 8,960 chips. Ironwood, announced in April 2025, puts 9,216 chips in a pod, with 4,614 trillion 8-bit FLOPs per second for each chip.
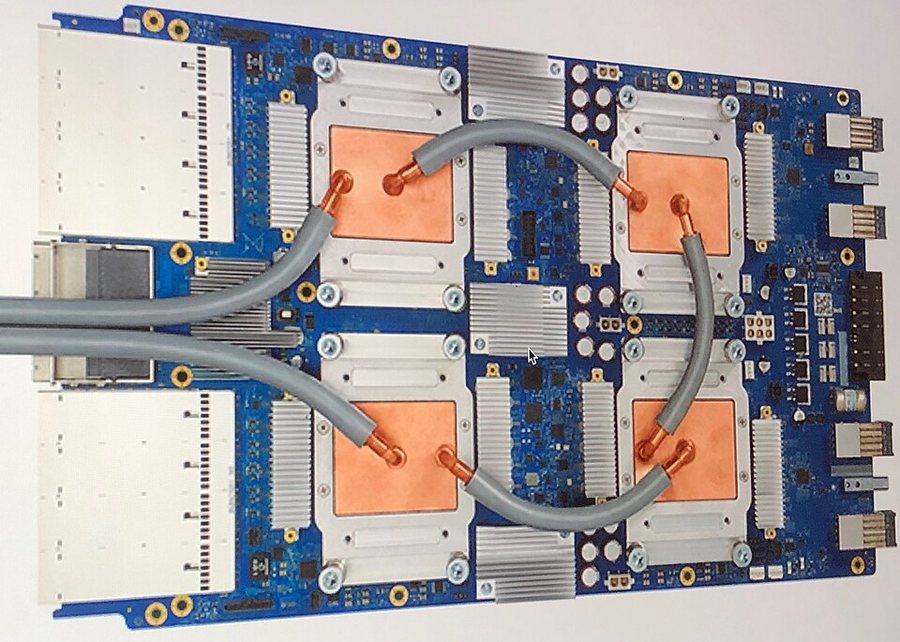
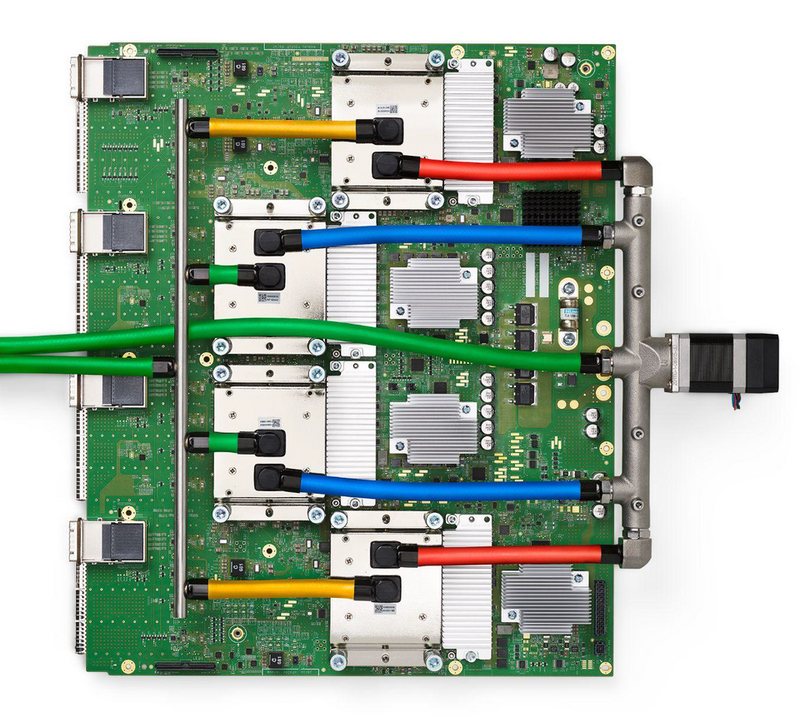
A TPU v3 board: four chips, each under a copper plate, cooled by liquid. Photo: Zinskauf, CC BY-SA 4.0, via Wikimedia Commons.A TPU v4 board, the chip generation that trained Gemini 1.5. Image: Norman P. Jouppi and colleagues, from their 2023 paper on TPU v4, CC BY 4.0, via Wikimedia Commons.
No run reaches the peak. Llama 3 reports an MFU of 38% to 43% in 16-bit numbers. With those figures, our script estimates that 3.8×1025 FLOPs on 16,384 H100s would take 63 to 71 days of pure training. That is our estimate, not a number Meta published.
A 405B model does not fit on one GPU, and one GPU would take centuries anyway. So the work is split in several ways at once.
With 4 stages and 4 micro-batches the pipeline is idle 3/7 of the time; with 32 micro-batches only 3/35 (8.6%). Numbers from our script.
Tensor parallelism comes from NVIDIA's Megatron-LM paper of 2019. It needs fast links, because GPUs must swap partial results inside every layer. So it usually stays within one server, where 8 GPUs are joined by NVLink.
Take Llama 3 8B's feed-forward matrix of 4,096 × 14,336. Four GPUs would each hold a 4,096 × 3,584 slice; eight would each hold 4,096 × 1,792. Pipeline parallelism has a different cost: at the start and end of each batch, some stages sit idle while they wait. Cut the batch into mmicro-batches that flow through p stages, and the idle share is
bubble=m+p−1p−1
With 4 stages and 4 micro-batches, 3/7=0.429 of the time is wasted. With 32 micro-batches it falls to 3/35=0.086. With 16 stages and 64 micro-batches it is 0.190. More micro-batches shrink the bubble but need more memory. MoE models add a fourth kind, expert parallelism: different experts on different GPUs, with tokens sent to wherever their experts live. DeepSeek-V3 spread each layer's routed experts over 64 GPUs.
Training needs far more memory than the weights alone. In mixed-precision training with the Adam optimizer, each parameter needs 2 bytes for its 16-bit weight, and 2 for its 16-bit gradient. It also needs 12 bytes of 32-bit optimizer state: a master copy of the weight and Adam's two running averages. That is 16 bytes per parameter.
For a 70B model, 16 bytes per parameter is 1,120 GB: the full memory of 14 GPUs with 80 GB each, before any activations. For 405B it is 6,480 GB. The ZeRO paper of 2019, from Samyam Rajbhandari and colleagues at Microsoft, gave the fix. Its example is a 7.5B model, which needs 120 GB of states. Sharded over 64 GPUs, each holds only 1.875 GB.
Halving the bits halves the memory traffic and roughly doubles the speed of the matrix units. In 2017, Paulius Micikevicius and colleagues at NVIDIA and Baidu showed that 16-bit training works. You keep a 32-bit master copy and scale the loss. The bf16 format, with its wide range, made the scaling unnecessary and became the default.
DeepSeek-V3 was the first very large open model trained mostly in FP8. Its report says it was the first to "validate its effectiveness on an extremely large-scale model". The trick is to scale small blocks of numbers separately, so one large value does not ruin the precision of its neighbours. The most sensitive parts, such as the embedding, the output head and the normalisation, stay in higher precision.
Almost every large model is trained with AdamW, from Ilya Loshchilov and Frank Hutter (2017). It is like a hiker who keeps a running average of the slope and of how bumpy the slope has been. Steps are large where the ground is steady and small where it is noisy.
gt is the gradient at step t. mt is the running average of gradients and vt of squared gradients, with decay rates β1 and β2. m^t and v^t are the same averages, corrected for starting at zero: divide by 1−β1t and 1−β2t. η (eta) is the learning rate and λ (lambda) the weight decay, which pulls every weight a little toward 0.
Take one weight w=1.0 with gradient g=0.5, η=0.001, β1=0.9, β2=0.95 and λ=0.1. Then m=0.05, v=0.0125, m^=0.5 and v^=0.25. The Adam step is 0.001×0.5/0.5=0.001, the decay adds 0.0001, and the new weight is 0.9989. With g=50, the step is still 0.001. Adam's first step has the size of the learning rate whatever the gradient's size, which is part of why it is stable.
DeepSeek-V3 used β1=0.9, β2=0.95 and weight decay 0.1, the same values as our example. The learning rate also changes during training. It starts at zero, rises in a straight line during a warm-up, and then falls.
t is the step, tw the length of the warm-up and T the last step. ηmax is the peak rate and ηmin the final one. The cosine falls from 1 to −1, so the rate glides from the peak to the floor, slowly at first, then faster, then slowly again.
Llama 3 405B used a peak of 8×10⁻⁵, 8,000 warm-up steps, and a cosine to 8×10⁻⁷ over 1,200,000 steps. Our script assumes that the 1.2 million steps include the warm-up. Then the rate is 4×10⁻⁵ at step 4,000 and 4.04×10⁻⁵ half-way through, at step 604,000.
The warm-up is too short to see at this scale: 8,000 of 1,200,000 steps. Llama 3 then annealed the rate to 0 over the last 40 million tokens. Curve from our script.
Other shapes are common. DeepSeek-V3 held its peak rate flat until 10 trillion tokens and decayed it along a cosine over the next 4.3 trillion. It ended with two short flat steps. Chinchilla's lesson about schedules still holds: the decay must match the planned length of the run.
Large runs are fragile. Google's PaLM paper of 2022 is unusually frank about it. For its 540B model, the team "observed spikes in the loss roughly 20 times during training", although gradient clipping was on. Their fix was to restart "from a checkpoint roughly 100 steps before the spike started" and skip "roughly 200–500 data batches". The same batches, given to an earlier checkpoint, caused no spike. So the cause was the data and the model's state together, not bad data alone.
Since then, labs have added tricks such as extra normalisation inside attention and limits on the size of attention scores. DeepSeek-V3 reports that "we did not experience any irrecoverable loss spikes or perform any rollbacks". Kimi K2 used a new optimizer, MuonClip, and reports pre-training on 15.5 trillion tokens "with zero loss spike".
Hardware fails too. In one 54-day stretch of Llama 3 training, there were 466 interruptions. Of these, 419 were unexpected, and about 78% of those were traced to confirmed or suspected hardware problems. Google's Gemini 2.5 report describes the same problem at TPU scale.
The most quoted cost in recent years comes from DeepSeek-V3, and it is often quoted wrongly.
Our script adds one more check. With C=6×37×109×14.8×1012=3.29×1024 FLOPs over 2,664K GPU hours, each GPU did about 343 trillion useful FLOPs per second. That leaves out attention, and it is our estimate, not DeepSeek's. Closed labs do not publish their training costs at all.
DeepSeek-V3 also trained with multi-token prediction. Besides the next token, a small extra module predicts the token after it.
Fabian Gloeckle and colleagues at Meta studied the idea in 2024. Their models trained with 4-token prediction were "up to 3× faster at inference". DeepSeek-V3 used a depth of 1, one extra token. It reports that the extra prediction is accepted 85% to 90% of the time, which gives about 1.8 times more tokens per second. The next section shows where that number comes from.
A model is trained once and served for months to millions of people, so its design is shaped by serving costs. GQA, MLA and MoE are all, in part, serving decisions. Three more tricks matter.
Writing one token at a time leaves a GPU mostly idle, because each step reads all the weights to make one token. Checking five guessed tokens costs about the same as making one. In 2022, Yaniv Leviathan and colleagues at Google showed a 2X-3X speed-up on T5-XXL "with identical outputs". If each guess is accepted with probability a and the draft guesses γ tokens, each pass of the large model yields on average
E[tokens per pass]=1−a1−aγ+1
a is the acceptance rate and γ (gamma) is the draft length. The formula counts the accepted guesses plus the one token the large model always adds. With a=0.8 and γ=4, that is 3.362 tokens per pass; with a=0.6, 2.306.
DeepSeek-V3 uses its MTP module as the draft, with γ=1. At a=0.85 the formula gives 1.850 tokens per pass, and at 0.9 it gives 1.900. That agrees with the 1.8 times speed-up the report gives. The inference series covers the method in depth.
Part 1 introduced quantisation: storing weights in fewer bits. A 70B model needs 140 GB at 16 bits, 70 GB at 8 bits and 35 GB at 4 bits. DeepSeek-V3's 671B parameters take about 671 GB in FP8, the format it was trained in. Many open models are now released in 8-bit or 4-bit versions, and serving systems run them with special matrix kernels.
Most users talk to small models. Labs make them by distillation, defined in Part 4: a small student learns from a big teacher's outputs. In pre-training, the student learns from the teacher's full probability over the next token, not only from the one token in the text. That is a far richer signal: it says that "cat" was likely, "dog" was nearly as likely, and "car" was not.
Google's open Gemma models follow the same path: the Gemma 3 report says that "all Gemma 3 models are trained with knowledge distillation". Meta used the 405B model to improve its smaller Llama 3 models in post-training, and Qwen3 describes "strong-to-weak distillation". The big model's main job in a family is often to teach the small ones.
Everything in this part comes from papers, technical reports and model cards. They differ widely in how much they say.
The open-weight labs publish the most: DeepSeek, Meta's Llama papers, Qwen, Kimi and above all the Allen Institute's Olmo, which also releases its data. Google's Gemini reports confirm the design in outline: sparse MoE, natively multimodal, long context, TPUs, distillation for the small models. OpenAI's GPT-4 report of 2023 set the closed pattern. It "contains no further details about the architecture (including model size), hardware, training compute, dataset construction, training method, or similar."
Question
Open-weight reports (DeepSeek, Llama, Olmo)
Closed frontier labs
Layer design
Full: norms, attention type, sizes
Google: "sparse MoE", little more; others: nothing
Parameter count
Exact, total and active
Not published
Training tokens
Exact or close
Not published
Data sources
Described; Olmo releases the data
Categories only ("web documents, code, images")
Hardware
Chip type and count
Google names TPU generations; others: little
Cost
DeepSeek: GPU hours for the final run
Not published
So, when you read a claim about a closed model's size or cost, ask where it comes from. If it is not in a lab's own report or model card, it is a guess or a leak, however often it is repeated.
Put the parts of this series side by side and you get the whole build of a frontier model in 2026.
A composite of the Llama 3, DeepSeek-V3, Gemini 2.5 and Olmo 3 reports. Closed labs confirm only parts of it.
Part 1 gave the parts list: the neuron, backpropagation, attention, the Transformer, the next-token loss. This part showed what they look like at scale. Part 2's classical methods live on inside the pipeline, as the small fast classifiers that filter data. Part 3 and Part 4 take over once the base model exists, and turn it into an assistant that reasons and uses tools.
The lessons repeat across all five parts. A good loss is not the same as a good model. Goodhart's law in Part 4 and the warning about loss in this part both show it. Scale wins, but only when the bottleneck moves: from compute to data, from data to memory, from memory to the cost of every answer. And most progress is a chain of fixes, each solving the limit the step before it left behind.
Data is the hardest limit. Good public text is close to used up, so the future depends on synthetic data, other kinds of data and better reuse. Whether a model can learn as much from text written by models as from text written by people is still an open question.
Architecture is less settled than it looks. Many 2025 and 2026 models mix in other layer types, such as linear attention, state-space layers and sparse attention, to make long contexts cheaper. The attention series covers them. DeepSeek-V3.2 added its own sparse attention. The SwiGLU paper's "divine benevolence" is still a fair summary of how many of these choices are made.
And scaling itself is changing shape. Pre-training compute keeps growing, but more of the total now goes to post-training and to thinking at answer time, as Part 4 showed. The next part of the curve may be drawn on that second axis.