SGLang Explained: How It Reuses Work, and How It Differs from vLLM
RadixAttention from a handbook example: KV reuse maths, real prefill timings, cache and scheduling simulations, and a fair comparison with today's vLLM.
You are building an assistant for a company's employee handbook. Every request includes the same instructions and the same handbook, followed by a question:
Request 1: instructions + handbook + "How much annual leave do I get?"
Request 2: instructions + handbook + "Can I carry unused leave forward?"
Request 3: instructions + handbook + "How do I apply for leave?"
The model must answer three different questions. But should it process the entire handbook from scratch three times?
SGLang helps avoid that repeated work. It is an inference engine: the software that loads a language model, accepts requests, runs the model, and sends back its answers. One of its central ideas, RadixAttention, finds prompt beginnings the model has already processed and reuses the saved computation.
vLLM, the engine from Part 3, also reuses repeated prompt beginnings, and in its current engine it does so by default. So the interesting question is not "which one caches?" Both do. The interesting questions are how each engine finds the saved work, what it throws away when memory runs out, in what order it runs waiting requests, and when any of this actually makes the user wait less.
We will follow the handbook assistant through those decisions, one at a time:
- What the engine saves, how big it is, and how much work it saves, with the maths and a real measurement on a real model.
- How SGLang finds saved work with a radix tree, and how it decides what to evict.
- How vLLM finds the same work with hashed blocks, and where the two designs really differ.
- Why the order in which requests run can matter as much as the cache itself.
- A second idea from the same paper: jump-forward decoding for JSON output.
- A fair comparison table for the versions available today, and a recipe to test both engines yourself.
1. What the inference engine does with your question
A model is a set of learned weights plus the computations that use them. Serving that model to many people takes more than running one forward pass. Someone has to queue incoming requests, put work into batches, allocate memory, and return generated tokens to the right user. That is the inference engine's job.
Our first handbook question passes through two main stages:
| Stage | What happens in our assistant | What the user sees |
|---|---|---|
| Prefill | The engine runs the model over the instructions, handbook, and question, building the state needed to answer. | Waiting for the answer to begin. |
| Decode | The model generates further answer tokens, using the prompt and the answer written so far. | The answer appearing a piece at a time. |
Prefill also provides the prediction used to select the first output token. Decode then continues from it. Part 1 explains these two stages in more depth.
SGLang accepts ordinary OpenAI-style serving requests, so you can put it behind an existing assistant. The original project also included a small Python language for describing connected model calls (for example "ask, then fork into three parallel judgements, then merge"). That frontend is optional; everything in this article is about the serving engine, which the paper calls the SGLang Runtime. Sources: SGLang documentation, original paper.
For now, focus on the first stage. Most of our second request's input is exactly the same as the first request's. To avoid processing it again, we need to know what can be saved.
2. Save the model's working state, not the answer
As the model reads the handbook, each attention layer computes arrays called keys and values, usually shortened to K and V. Later token positions use them to read information from earlier positions.
Within one answer, this is already useful. When generating the next word, the model reuses the saved state for the prompt and the answer so far. It does not rebuild that whole history at every step (Part 2 measured this).
Now extend the idea across requests. After answering the annual-leave question, keep the handbook's KV state. When the carry-forward question arrives, reuse the handbook state and compute only the new question's state.
The cached object is not "the answer to the annual-leave question." It is the model's representation of the shared beginning. Different questions can use it to produce different answers.
Why the later question does not change the earlier handbook
A standard causal language model reads in one direction: a token position can use itself and earlier positions, but cannot look at later positions.
In our prompt, the handbook comes before the question. While processing a handbook token, the model cannot look ahead at the question. Changing that later question therefore does not change the handbook's keys and values, provided the model, preceding tokens, and positional setup stay the same.
This arrangement can share the handbook:
instructions → handbook → question that changesThis one usually cannot share the handbook across different questions:
question that changes → instructions → handbookIn the second arrangement, the handbook can attend to a different earlier question, so its states may differ. Changing a timestamp, chat template, or tool definition near the beginning can also shorten the reusable prefix. Preserve the intended meaning when arranging a prompt; do not move information blindly just to improve a cache-hit number.
A little maths: the same stored values, a different answer
Attention reads stored values by assigning them weights. A new query determines those weights. You can think of a query as what the current position wants to find in earlier positions.
Consider just two stored positions. To keep the arithmetic small, let their keys be 0 and 1, and their values be 2 and 6. Each vector has only one component in this example.
With query 0, both key matches score 0. Their attention weights are equal:
Now choose query , the number whose exponential is 3. The scores become 0 and . Softmax exponentiates them, giving 1 and 3, then divides by their sum:
The weighted result is now:
The keys and values stayed the same. The query changed, so the result changed. Reusing KV does not force two questions to get the same answer. These two scalar calculations illustrate the attention operation; a language model repeats it with large vectors, many heads, and many layers.
The companion code runs this example, and it also checks two complete causal-attention layers: reusing an unchanged prefix agrees with recomputing the full sequence to floating-point precision (largest difference ), while deliberately reusing a changed prefix does not (largest difference 0.95). Section 4 repeats the check on a real model.
3. How big is the saved state?
Before deciding to keep the handbook's KV state around, ask what it costs to keep. Every token stores one key vector and one value vector in every layer, for every KV head.
The idea. Multiply the things a token stores.
Symbol by symbol. The 2 counts the two arrays, K and V. is the number of layers. is the number of KV heads per layer (with grouped-query attention this is smaller than the number of query heads, Part 2). is the length of one head's vector. is bytes per number: 2 for BF16 or FP16.
Worked numbers for Llama 3.1 8B (32 layers, 8 KV heads, head size 128, BF16, the same model as Parts 2 and 3):
Our handbook plus instructions is about 6,000 tokens. Stored once, that is
The same formula for the two Qwen models used in this series, from their published configurations (Qwen2.5-0.5B: 24 layers, 2 KV heads, head size 64; Qwen2.5-7B-Instruct: 28 layers, 4 KV heads, head size 128):
| Model | Calculation | Per token | 6,000-token handbook |
|---|---|---|---|
| Qwen2.5-0.5B | 12 KiB | 70 MiB | |
| Qwen2.5-7B | 56 KiB | 328 MiB | |
| Llama 3.1 8B | 128 KiB | 750 MiB |
What this does and does not include. It is the KV payload only: no model weights, no temporary working memory, no page-table overhead. Quantized caches (for example FP8, which halves ), sliding-window layers, and multi-GPU sharding all change the accounting. The point to carry forward: a cached handbook is not free. It occupies memory that could otherwise hold more running requests, and that is why eviction (Section 7) exists.
4. What reuse saves: compute first, then time
Counting the arithmetic
Suppose the cache already holds a prefix of tokens (instructions and handbook), and the new question adds suffix tokens. How much prefill work is left?
The idea. Each new token does two kinds of work. It is multiplied by every weight in the model, and in every layer its query is compared with the keys of every earlier position (and the result is used to mix their values).
The equation. For new tokens on top of cached ones,
Symbol by symbol. is the number of non-embedding weights; each weight costs one multiply and one add per token, hence . is the number of layers and the query width (heads × head size). New token attends to positions; summing over gives query-key pairs. Each pair costs for the score and for mixing the value, hence per pair.
Without a cache, the request costs . With the prefix cached, it costs . The saving is the difference, and the speedup in arithmetic is their ratio:
Notice what the cached version still pays: the term. The new question still attends to every cached handbook token. Reuse removes the handbook's own computation, not the handbook from attention.
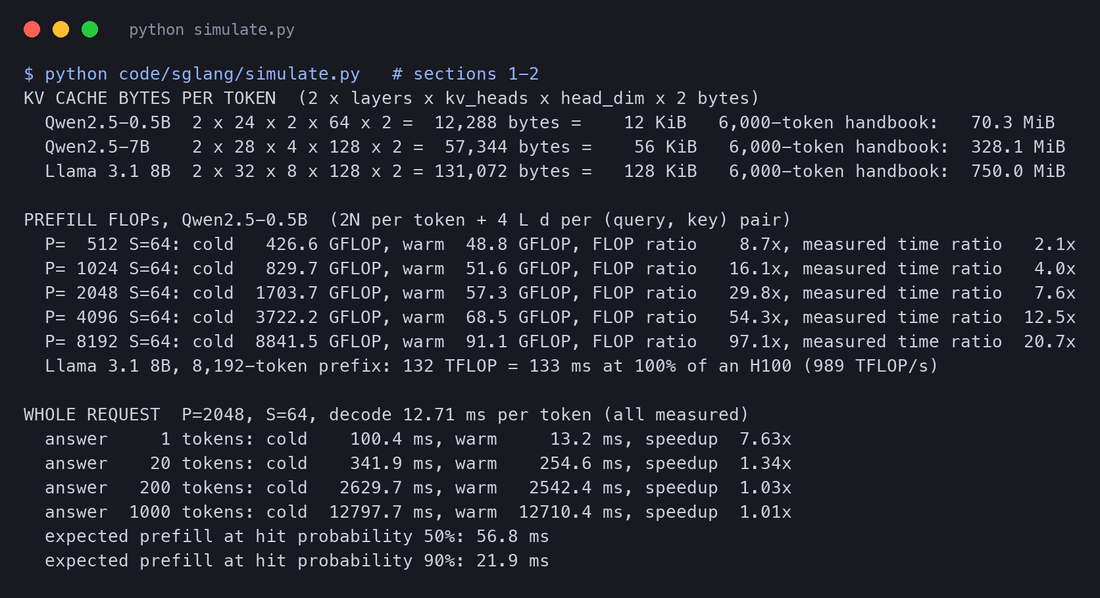
Worked numbers for Qwen2.5-0.5B ( non-embedding weights, , ), with a 2,048-token handbook and a 64-token question:
That is a 30x reduction in arithmetic. For scale, the same arithmetic for Llama 3.1 8B with an 8,192-token prefix is about 132 TFLOP, which would take 133 ms even at 100% of an H100's dense BF16 peak of 989 TFLOP/s (a bound, not a measurement).
The companion script prints these numbers for every prefix length, together with the KV sizes from Section 3 and the whole-request arithmetic used later in this section:
Measuring the time on a real model
Arithmetic is not time. So I ran the operation itself: Qwen2.5-0.5B in BF16 on an Apple M5 Pro GPU through PyTorch, the setup used in Parts 1 to 3. Cold means prefill handbook and question from nothing. Warm means the handbook's KV cache is already there and only the question is prefilled on top of it. Token IDs are random, because the content of the text does not change how long the arithmetic takes. Each time is the median of 9 runs after 3 warm-up runs.
_, prefix_cache = prefill(prefix)                        # done once, then kept
cold_logits, _ = prefill(torch.cat([prefix, suffix], 1)) # everything from scratch
warm_logits, _ = prefill(suffix, copy.deepcopy(prefix_cache))  # only the new tokens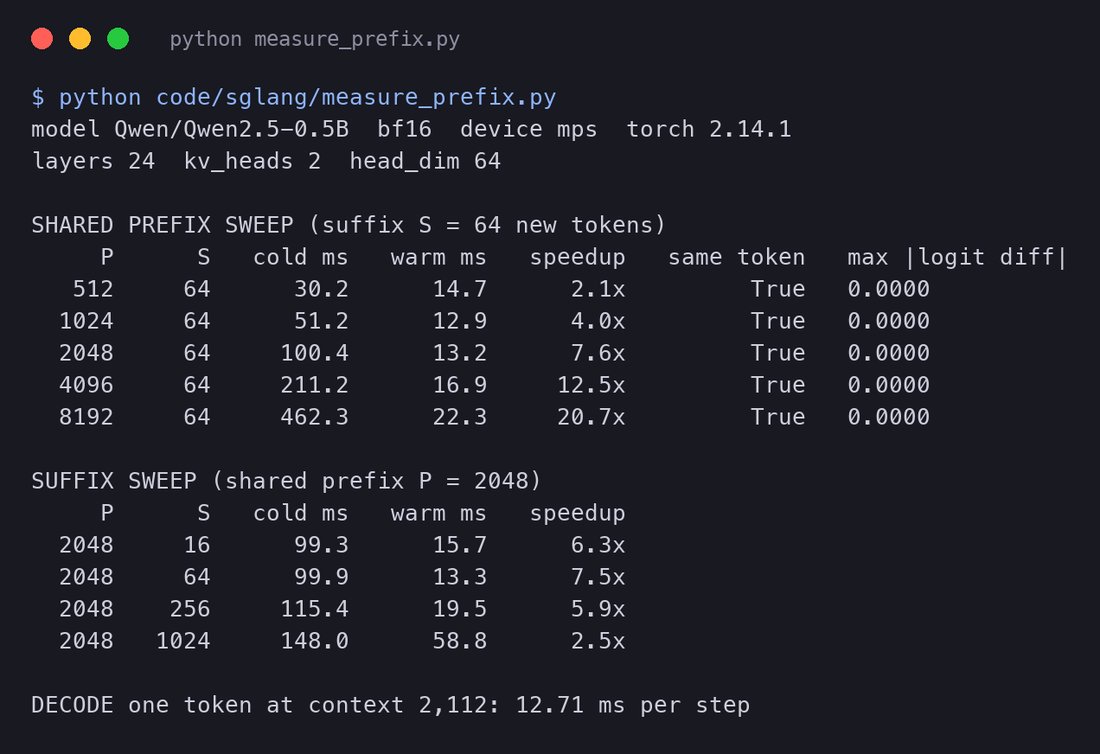
Three things to read from this run:
- The answer did not change. In every case the cold and warm runs chose the same next token, and the largest difference between their output scores was 0.0000 to four decimal places. Reuse is the same arithmetic done once, not an approximation.
- The saving grows with the shared prefix, from 2.1x at 512 tokens to 20.7x at 8,192 tokens, because cold prefill grows with while the warm pass stays small.
- The time saving is smaller than the arithmetic saving. At the arithmetic falls 30x, but the time falls 7.6x. A 64-token pass on this GPU costs about 13 ms no matter how few FLOPs it has, about the same as one decode step (12.71 ms in the same run). Part 1 explained why: small passes are limited by reading the weights from memory and by fixed overheads, not by arithmetic. That is also why was no faster than here.
To use these timings in simulations later, I fitted a simple cost model to all nine cold and warm measurements:
with new tokens on top of cached ones. The 11.0 ms constant is that fixed floor; the last term is attention to everything already there. It fits the cold runs within 10% and every point within 30% (the worst is the warm run at , 22.3 ms measured against 15.5 ms predicted). It is good enough to compare scheduling orders on this machine, and not a model of any other GPU.
What the user actually waits for
Prefill is only the beginning. The whole request costs the time to the first token (TTFT) plus one decode step for every later answer token (time per output token, TPOT):
Prefix reuse shrinks TTFT and leaves TPOT alone, so the speedup of the whole request is
where is the decode step. With the measured values for a 2,048-token handbook ( ms, ms, ms):
| Answer length | Cold request | Warm request | Speedup |
|---|---|---|---|
| 1 token | 100.4 ms | 13.2 ms | 7.63x |
| 20 tokens | 341.9 ms | 254.6 ms | 1.34x |
| 200 tokens | 2,629.7 ms | 2,542.4 ms | 1.03x |
| 1,000 tokens | 12,797.7 ms | 12,710.4 ms | 1.01x |
Same cache hit, very different value. For a "yes / no / which section" style answer it is a 7.6x faster response. For a long essay it barely matters for the person waiting, although the GPU time saved can still be spent on other people's requests. vLLM's own documentation says the same thing about its prefix cache:
5. How SGLang finds the saved beginning: RadixAttention
Our assistant may answer thousands of questions. Some requests share the whole handbook; others share only the instructions. Some are follow-up turns of the same chat and share the whole previous conversation. Scanning every old prompt to find the longest match would be slow. We need an index.
Let us build one. For this small example, six token IDs stand for our shared instructions and handbook:
shared beginning: 10 11 12 13 14 15
first question:                     20 21
second question:                    30 31
These are invented IDs for seeing how the algorithm works, not a real tokenizer's encoding of the handbook.
First request. The tree is empty. Compute all eight positions and record the sequence as one edge, pointing at its saved KV.
Second request. Follow the stored sequence from the root. The first six IDs match. The next ID is 30 instead of 20, so split the edge at that point. Reuse the six matching positions and compute the two new ones.
The tree says where to find the states. It is not the large array of states itself: the index lives on the CPU, while the KV tensors live in GPU memory. Splitting an edge changes the index only; the shared prefix is not recalculated or copied.
Run the three-request example
Here is the small radix-tree implementation from the companion code in use:
from experiments import Radix

prefix = [10, 11, 12, 13, 14, 15]
prompts = [
    prefix + [20, 21],
    prefix + [30, 31],
    prefix + [20, 40],
]
cache = Radix()

for number, prompt in enumerate(prompts, 1):
    reused = cache.match(prompt)
    print(f"request {number}: reuse {reused}, compute {len(prompt) - reused}")
    cache.insert(prompt)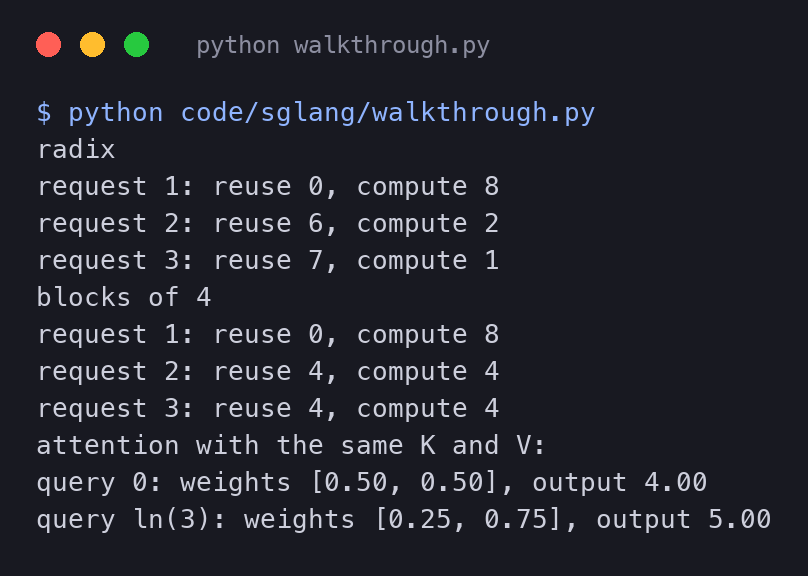
The third request is worth looking at. It shares the six-token beginning and token 20 with the first request. Matching continues into that branch, stopping only when 40 differs from 21. The reusable part is discovered from the tokens; it does not have to end at a boundary we called "the handbook."
This example runs the lookup and insertion logic on the CPU. It counts token positions that need computing; it does not run a model for them. The full Radix implementation includes the edge splitting just illustrated, and it is checked against a brute-force longest-common-prefix search on 600 random requests.
The paper's own picture
The paper draws the same process for a richer mix of traffic: two chat sessions, a batch of few-shot questions, and several samples of one question.
The SGLang team's launch post summarised which kinds of programs produce this sharing. Our handbook assistant is pattern (a); a support chat is pattern (c).
6. How much memory the tree shares
Reuse saves computation once. Sharing saves memory for as long as requests run together. If 32 people are asking about the handbook at the same moment, should there be 32 copies of its KV cache in GPU memory?
The idea. In a radix tree, every token position is stored once, on exactly one edge, however many requests pass through that edge.
The equation. Without sharing, memory is the sum of the request lengths. With a tree, it is the sum of the edge lengths:
Worked numbers. Take 32 active requests, each with 512 instruction tokens, one of 4 handbook sections of 1,536 tokens, and its own 64-token question. Each request is tokens.
That is 7.8x less KV memory. Multiply by bytes per token from Section 3: on Llama 3.1 8B it is 8.25 GiB without sharing against 1.06 GiB with the tree; on Qwen2.5-0.5B, 0.77 GiB against 0.10 GiB.
More free memory means more requests fit in a batch, and Part 1 showed that bigger decode batches mean more tokens per second. That is the second, less obvious benefit of prefix sharing.
Be careful what this compares against. "No sharing" means an engine that copies the prefix into every request. vLLM shares too: identical full blocks are stored once and reference-counted (Part 3). So against vLLM the difference is not 7.8x; it is at most the partial-block tokens that blocks cannot share (Section 8).
7. When the cache fills up: LRU eviction
GPU memory is finite. Sooner or later, keeping one more handbook means dropping something else. The paper's rule is simple to state: evict the least recently used leaf first, and never evict anything a running request is using.
The equation. Give every node a last-access time and a reference count (how many running requests use it). While memory used exceeds capacity , remove
Why leaves only, and why it is safe. Every time a request uses a node, it walks through all the node's ancestors and touches them too. So a parent is always at least as recent as any of its children:
Plain LRU would therefore never want a parent gone before its children anyway. Restricting eviction to leaves keeps the tree well formed, and the shared handbook, which sits above many questions, can only be evicted after every question below it has gone.
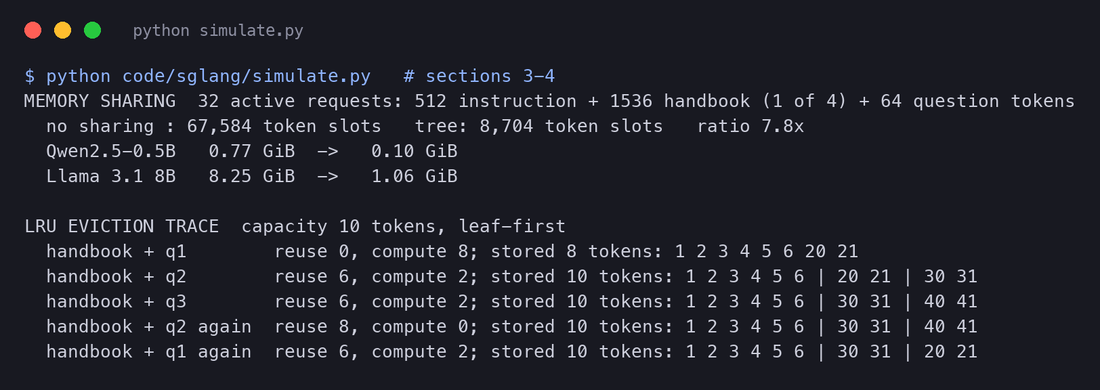
A worked trace, with room for only 10 tokens:
Current SGLang keeps exactly this rule as its default and adds alternatives. Its documentation states the leaf-first walk directly:
One detail matters for the comparison later: in the source we checked, SGLang's RadixCache.evict frees a chosen leaf whole. If the least recently used leaf is a 1,500-token handbook section, all 1,500 tokens go at once. Keep that in mind for Section 8.
So a second handbook request can reuse the first request's work only if that work is still in the cache. A matching prompt alone does not guarantee a hit.
8. Hit rate and the expected saving
How do you know whether all this is working? The paper defines the number to watch:
It is a token-weighted rate: a request that reuses 2,000 of its 2,064 tokens counts far more than one that reuses 10 of 50. Two consequences follow directly.
Expected computation. The prompt tokens that still need prefill are
Expected first-token time. Suppose each handbook request either finds the handbook cached (probability ) or does not. With the measured times from Section 4,
At that is ms; at it is 21.9 ms. The expected time falls in a straight line as the hit probability rises, so each extra percentage point of hits is worth the same amount: here about 0.87 ms per point.
What hit rates happen in practice? The paper reports one production data point:
9. How vLLM handles the same two requests
vLLM also reuses prefixes, and in its current engine this is on by default: enable_prefix_caching: bool = True in the version we checked. It finds saved work differently. It cuts every sequence into fixed-size blocks (16 tokens by default, the same blocks PagedAttention stores, Part 3) and gives each full block a hash: a compact fingerprint used to look it up.
The equation. With block size , block 's key is
The reusable length for a new prompt is the longest run of blocks whose keys are all in the cache:
With an unlimited cache, this equals the radix tree's exact match rounded down to whole blocks, . The companion code checks that identity on 300 random requests for each of .
Use four-token blocks on our second request to see the rounding:
How much does rounding cost?
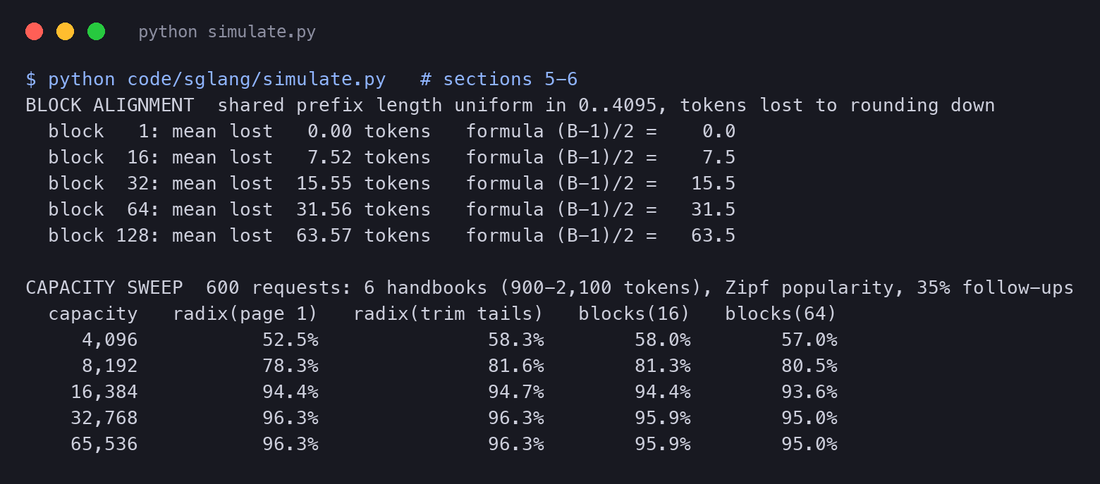
If the point where two prompts diverge falls at a random place inside a block, the reuse lost to rounding is , which is equally likely to be any of :
For vLLM's default , that is 7.5 tokens per request on average; the simulation over 100,000 random prefix lengths gives 7.52. Next to a 2,048-token handbook it is noise. It matters only when the shared parts are short, or very many short shared pieces are stitched together.
This does not mean SGLang always reuses individual tokens while vLLM always uses blocks. SGLang's page size defaults to one token on NVIDIA GPUs in the source we checked, but it is configurable, some backends and models set larger pages, and its matcher rounds down to the page size exactly like blocks (RadixKey.match_at).
The vLLM picture: lookup, then allocation
vLLM's design page walks through a small example with four-token blocks. Here a second request shares its first 10 tokens with the first:
Two more vLLM details complete the picture. When a whole prompt is already cached, vLLM still recomputes its last token, because it needs that position's output scores to pick the first answer token (max_cache_hit_length = request.num_tokens - 1). Our simulations apply the same rule to both caches. And vLLM's eviction is also LRU, with a twist:
Does the tree win when memory is tight?
It is tempting to assume the radix tree must give more hits. So I simulated both caches on one trace, under memory pressure. The trace has 600 requests: 300 instruction tokens, then one of six handbooks of 900 to 2,100 tokens (picked with Zipf-like popularity), then a 20 to 90 token question, with 35% of requests being follow-ups in an existing chat (so the previous answer becomes part of the prefix). Answers of 40 to 160 tokens are cached too. Requests run one at a time. Four caches see the same trace:
- radix, page 1: leaf-first LRU, evicting a whole leaf, as in SGLang;
- radix, trims leaf tails: an ablation that shortens the LRU leaf from its end by only as many tokens as needed;
- blocks of 16 and blocks of 64: hash-chained full blocks with an LRU free queue in reverse order, as in vLLM.
| Capacity (tokens) | Radix, page 1 | Radix, trims tails | Blocks of 16 | Blocks of 64 |
|---|---|---|---|---|
| 4,096 | 52.5% | 58.3% | 58.0% | 57.0% |
| 8,192 | 78.3% | 81.6% | 81.3% | 80.5% |
| 16,384 | 94.4% | 94.7% | 94.4% | 93.6% |
| 32,768 | 96.3% | 96.3% | 95.9% | 95.0% |
Read it carefully, because it cuts against the easy story:
- With enough memory, the index hardly matters. At 32,768 tokens every cache is within 1.3 points. The radix tree's small edge is the block-rounding loss computed above.
- Under memory pressure, the block cache won in this simulation. At 4,096 tokens, it kept 58.0% against 52.5%. The ablation shows why: a radix cache that may trim a leaf's tail gets 58.3%. Whole-leaf eviction throws away the useful start of a long handbook together with its end; block eviction peels a sequence from its end, block by block.
- This is a simulation, not an engine benchmark. It runs one request at a time, has no concurrency, no batching, no real memory pool shared with running requests, and only one trace. It cannot tell you which engine has the higher hit rate on your traffic. What it does show is that "tree versus hash table" is the wrong question; granularity of eviction, block size and what you count as capacity matter more.
A simpler workload with every shared part a multiple of 16 tokens and unlimited memory shows the "enough memory" end of this table cleanly: both indexes compute exactly the same 6,144 tokens instead of 86,016.
Where PagedAttention fits
Part 3 introduced vLLM's PagedAttention. It is easy to mix up two different jobs:
| Job | Question it answers |
|---|---|
| Paged KV storage | Where in memory should this request's keys and values go? |
| Prefix-cache lookup | Have these token positions already been computed, and where is their saved state? |
A radix tree can point to KV stored in pages; SGLang's paper says RadixAttention is "compatible with" paged attention and continuous batching, and its pages are simply one token long by default. RadixAttention does not replace the attention computation or make paging unnecessary. It is an index and an eviction policy on top of paged storage.
10. When the assistant gets busy: the order of requests matters
So far, one request finished before the next started, in arrival order. A real service has a queue. When several requests are waiting, the scheduler chooses which runs next, and that choice decides what is still in the cache when each request runs.
The paper's idea: longest prefix first
The equations. If one server prefills waiting requests one at a time, and request in the chosen order takes , then request gets its first token at
Every request's time is added into the wait of everyone after it. A schedule that turns misses into hits early shortens not only those requests but every request behind them. And the lower bound from the theorem says the total computed tokens can never go below .
A simulation: four handbooks, room for two
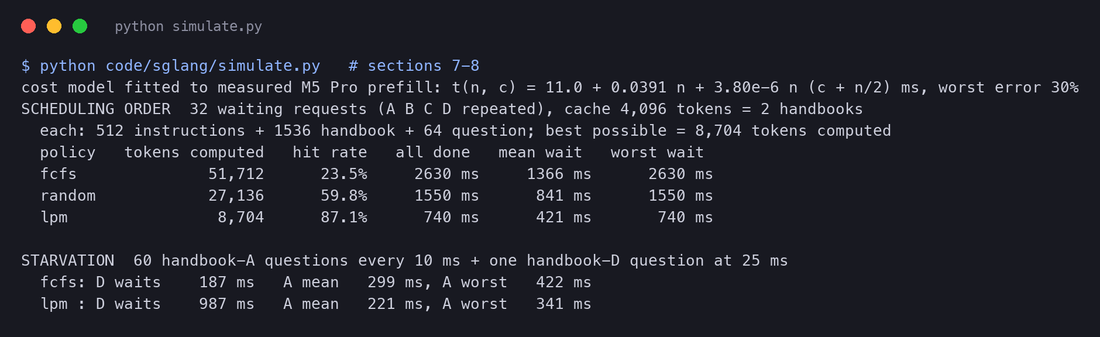
Now 32 handbook questions are waiting at once, arriving in the order A B C D A B C D and so on (four different handbook sections). Each request is 512 instruction tokens, a 1,536-token section and a 64-token question. The cache holds 4,096 tokens: the instructions plus two sections and a few questions. One prefill runs at a time, timed with the cost model from Section 4.
The best possible work is the size of the tree: tokens.
| Order | Tokens computed | Hit rate | Last request done | Mean wait | Worst wait |
|---|---|---|---|---|---|
| FCFS (arrival order) | 51,712 | 23.5% | 2,630 ms | 1,366 ms | 2,630 ms |
| Random | 27,136 | 59.8% | 1,550 ms | 841 ms | 1,550 ms |
| LPM (longest prefix first) | 8,704 | 87.1% | 740 ms | 421 ms | 740 ms |
LPM reached the theorem's lower bound exactly: 8,704 tokens. The arithmetic of the timeline is easy to check. Under FCFS the first request costs about 102 ms and each of the other 31 misses its section and costs about 82 ms (instructions still cached), so ms. Under LPM there are four section misses and 28 hits of about 14 ms: ms. The mean wait falls from 1,366 ms to 421 ms because, by the formula above, every saved millisecond early in the queue is saved again for everyone behind it.
Arrival order was the worst possible case here on purpose: it cycles through more sections than fit in the cache, which is exactly the "cache thrashing" the paper describes. With arrivals already grouped, FCFS would do as well as LPM.
The price: starvation
Now a different situation. Handbook A is popular: 60 A questions arrive, one every 10 ms. Each takes about 14 ms with A cached, so a queue builds up. One handbook-D question arrives at 25 ms. D is not cached and needs a full section prefill.
| Order | D question waits | A questions, mean | A questions, worst |
|---|---|---|---|
| FCFS | 187 ms | 299 ms | 422 ms |
| LPM | 987 ms | 221 ms | 341 ms |
LPM made the average A request faster but made the D user wait 5.3 times longer, until the A stream ended. In a real service with a never-ending A stream, D could wait much longer. That is the starvation the paper warns about.
What this simulation can and cannot show. It isolates the effect of order on hit rate and waiting, with one server, one prefill at a time, no decode and no batching. Real engines batch many prefills and decodes per step (Part 3), so the gaps would be smaller and shaped differently. The direction of both effects, fewer misses with grouping and longer waits for the unlucky request, is what carries over.
What the engines do today
This is where the paper and the current code differ, and where the comparison is most often overstated.
- SGLang's default is first come, first served. The
--schedule-policyflag defaults tofcfsin the source we checked (schedule.py). The paper's longest-prefix-match is available aslpm, alongsidedfs-weight,lof,priority,random,routing-keyand others. - Even with
lpm, very long queues fall back to FCFS. When more than 128 requests are waiting, SGLang turns off the prefix matching and sorting because it is expensive (_determine_active_policy). - SGLang also has an in-batch trick. If several waiting requests share a prefix that is not cached yet, it can run one of them first so the others hit the cache afterwards (the "in-batch prefix caching" check in the same file).
- vLLM's scheduler offers
fcfsandpriority(SchedulerPolicy); neither sorts the queue by cached prefix length.
Several servers: route to the warm one
With several replicas, placement is the same problem one level up. A request sent to the worker that already holds its handbook avoids rebuilding it; a request sent round-robin probably lands on a cold worker.
11. A second idea from the paper: decode JSON faster
Suppose the assistant must answer in a fixed format so another program can read it:
{"employee": "Asha Rao", "leave_type": "annual", "days": 12}Engines enforce such a format with constrained decoding: the schema becomes a grammar or a finite state machine (FSM), and at each step tokens that would break the format get probability zero. Both SGLang and vLLM do this today through grammar libraries (SGLang: xgrammar by default, also outlines and llguidance; vLLM: auto, choosing between backends such as xgrammar and guidance).
The SGLang paper noticed a waste. Much of a JSON answer is not a choice at all: after { the schema forces "employee": ". Decoding those characters one token per forward pass spends a full model step on text the model has no say in.
The equation. If an answer has forced tokens grouped into forced runs, and tokens the model chooses, then
The saving is passes. It is large when forced runs are long (verbose keys, fixed templates) and small when the model writes most of the text.
Worked numbers. I tokenized our JSON answer with the real Qwen2.5 tokenizer and marked each token as forced or chosen. The model chooses where the free string Asha Rao ends, so its closing quote counts as a choice; after the fixed value annual the closing quote is forced.
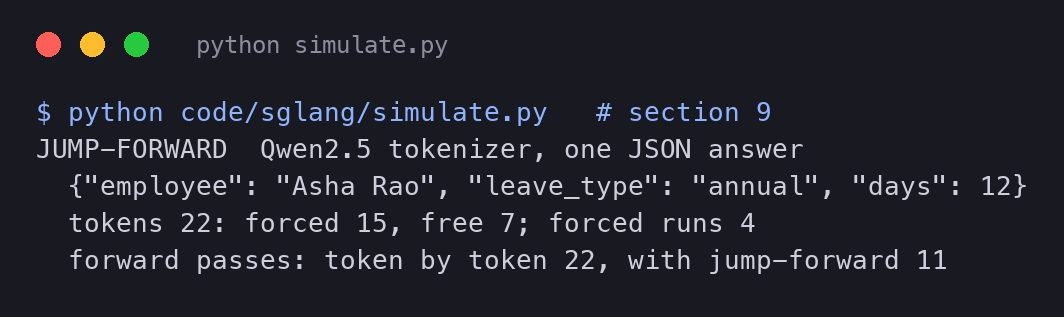
Look at the token ", after Rao: one token holds the model's closing quote and a forced comma. Tokens do not respect the grammar's boundaries, so a real implementation must handle text that is half forced and half chosen. The SGLang team's post on this method describes exactly that "tokenization boundary" problem and re-tokenizes the jumped text.
Current status, stated carefully. In the SGLang source we checked, the grammar backends still define a try_jump_forward hook (base_grammar_backend.py), but no scheduler code calls it. So treat jump-forward decoding as a published idea with a measured result, not as something the default server does for you today. Both engines' structured-output speed now comes mainly from fast grammar engines such as XGrammar; the SGLang v0.4 post reported up to 10x faster structured outputs from adopting it. Valid JSON still needs correct facts, so check those separately. Sources: SGLang structured outputs, vLLM structured outputs.
12. Two more things a busy server needs
Prepare the next batch while the GPU runs the current one
Even when KV reuse works, the GPU can sit idle while the CPU prepares the next batch: matching prefixes, allocating memory, building the input arrays.
The equation. If CPU preparation takes and GPU execution takes per batch, a serial loop costs per batch, and an overlapped loop costs once it is running. With ms and ms, 100 batches take 1,000 ms serially and ms overlapped.
Keep more handbooks outside GPU memory
SGLang's HiCache extends the radix cache into host memory and optional storage backends (off by default, --enable-hierarchical-cache). vLLM has a native CPU KV offloading option (kv_offloading_size) and connectors such as LMCache. A host-memory hit still has to copy the KV back to the GPU before it can be used. Source: HiCache design.
The decision rule. Fetching saved work pays off only if moving it is cheaper than recomputing it:
For a 1 GiB prefix (8,192 tokens on Llama 3.1 8B) at an assumed effective 25 GB/s, the copy alone takes ms. If recomputing that prefix takes 20 ms, a blocking copy loses; if it takes 200 ms, the copy wins. Lookup, allocation and contention add costs, and overlapping the copy with other work can hide some of them. The 25 GB/s is an assumption for the arithmetic, not a measurement.
13. What the paper measured, and what it does not tell you today
The headline numbers from the paper are real, but they compare SGLang with the vLLM of late 2023.
The same evaluation also measured what the tree costs when nothing is shared:
14. So how does SGLang differ from vLLM?
We can now compare the engines on the problems we have actually worked through. Defaults are from the source code checked on 8 October 2026 (SGLang b2cb249, vLLM c23ca06) and can change between releases.
| Problem | SGLang | vLLM |
|---|---|---|
| Prefix caching on by default? | Yes (--disable-radix-cache turns it off) | Yes (enable_prefix_caching=True) |
| How saved work is found | Radix tree over token IDs | Hash table of chained full-block hashes (SHA-256 by default) |
| Reuse granularity | Page size; 1 token by default on NVIDIA GPUs | Block size; 16 tokens by default |
| Generated tokens cached? | Yes | Yes (full blocks) |
| Eviction | Leaf-first, whole leaf; lru default, also lfu, slru, priority, tlru | LRU free queue; a request's blocks freed last block first |
| Isolation between tenants | Extra key and cache salt in the radix key | cache_salt and extra hashes in the block key |
| Queue order | fcfs default; lpm and others opt-in; LPM falls back to FCFS above 128 waiting | fcfs or priority |
| Routing across replicas | cache_aware policy in SGLang Model Gateway, the router introduced in v0.4 | Not part of the engine; separate routing projects |
| CPU and GPU overlap | Overlap scheduler, on by default | Async scheduling, on by default when compatible |
| KV beyond GPU memory | HiCache (host memory, storage backends), off by default | Native CPU offloading, LMCache and other connectors |
| Structured output | Grammar backends, xgrammar default; jump-forward hook not called | Grammar backends, auto (for example xgrammar, guidance) |
What this table says, in one paragraph: both engines avoid repeated prefill for shared beginnings, by default. The real differences are smaller and more specific than "tree versus no tree": token-level versus block-level matching (a few tokens per request), whole-leaf versus block-by-block eviction (which mattered under tight memory in our simulation), an optional cache-aware queue order in SGLang (with a starvation risk), and a cache-aware router. Everything else on the list exists in both, under different names.
For our handbook assistant, the useful question is: which configuration answers our actual requests within the target time using less hardware? Test at least these three cases:
- One shared handbook, many questions. This shows the value of retaining and reusing the prefix.
- Many unrelated handbooks, more than fit in memory. This tests eviction and, for SGLang, whether
--schedule-policy lpmhelps or starves anyone. - Long generated answers. This shows whether decoding dominates once input work is reduced.
Use the same model snapshot, hardware, request trace, and generation settings. Record time to first token, time to finish, completed requests per second, errors, answer quality and the engines' own cache-hit metrics. Test both a fresh cache and a deliberately warmed one, and report the slowest requests, not only the average. There is no universal winner independent of workload.
15. Try it yourself
The companion code contains every script, saved output and figure source used above.
The CPU examples and simulations
From the repository root:
python3 -m venv /tmp/sglang-article-env
/tmp/sglang-article-env/bin/pip install -r code/sglang/requirements.txt
/tmp/sglang-article-env/bin/python code/sglang/walkthrough.py     # three-request trace, attention example
/tmp/sglang-article-env/bin/python code/sglang/experiments.py     # 64-request workload, attention equivalence
/tmp/sglang-article-env/bin/python code/sglang/simulate.py        # sections 3 to 11 of this article
/tmp/sglang-article-env/bin/python -m unittest discover -s code/sglang -p 'test_*.py'
simulate.py needs the saved timings in results/measure_prefix.json and the Qwen2.5 tokenizer (for the JSON example). The unit tests check both caches against a brute-force longest-prefix search, the leaf-first eviction rule, reference-count locking, and block eviction order.
The real prefill measurement
measure_prefix.py needs PyTorch and Transformers, and runs on Apple GPUs (mps), NVIDIA GPUs (cuda) or slowly on a CPU:
python code/sglang/measure_prefix.pyIt prints the table shown in Section 4 and saves the hardware, versions and every timing to results/measure_prefix.json.
Then try a real model server
On a compatible GPU machine, install each engine in its own environment using its SGLang installation guide or vLLM installation guide. Use the same downloaded model snapshot for both, and start one server at a time on the same GPU:
# SGLang (radix cache is on by default; add --schedule-policy lpm to test cache-aware order)
python -m sglang.launch_server \
  --model-path /models/qwen2.5-0.5b-instruct-snapshot \
  --served-model-name comparison-model \
--host 127.0.0.1 --port 30000# vLLM (prefix caching is on by default in current versions)
vllm serve /models/qwen2.5-0.5b-instruct-snapshot \
--served-model-name comparison-model \
--host 127.0.0.1 --port 8000Check the installed version's --help for available flags. The official request guides cover SGLang and vLLM.
Then send two different questions after the same handbook-like prefix:
python3 code/sglang/probe_server.py \
  --url http://127.0.0.1:30000 --model comparison-model \
  --output /tmp/sglang-probe.json
Use port 8000 and a different output file for vLLM. The probe saves the answers, time to first nonempty text, total streaming time, and token usage when the server supplies it.
This checks that requests work. Two requests cannot establish a throughput winner, and a faster second response alone does not prove a cache hit; read the engine's cache metrics. The GPU commands are a reproduction recipe and were not run for this article, because no NVIDIA GPU was available. The README records what was run and the limits of each experiment.
The whole part, on one page
| Question | Answer | Where the number comes from |
|---|---|---|
| What is saved? | The prefix's keys and values, not the answer | Causal attention; exact match on a real model |
| How big is it? | per token: 128 KiB on Llama 3.1 8B, 750 MiB per 6,000-token handbook | Arithmetic from model configs |
| How much prefill does it save? | 30x fewer FLOPs, 7.6x less time at , | Measured, Qwen2.5-0.5B on an M5 Pro |
| Does the whole request get faster? | 7.6x for a 1-token answer, 1.03x for 200 tokens | Measured prefill and decode, combined |
| How much memory does sharing save? | $\sum_r | r |
| Radix tree or hashed blocks? | Same reuse with ample memory; under pressure, eviction granularity matters more | Simulation, one trace |
| Does request order matter? | LPM reached the 8,704-token optimum (87.1% hits) against 23.5% for FCFS, but one request waited 5.3x longer | Simulation with a measured cost model |
| What did the paper report? | Up to 6.4x throughput against vLLM v0.2.5 (2023); 74.1% hits and 1.7x faster first token in Chatbot Arena | Reported by the authors |
Return to the three questions at the start. Both SGLang and vLLM can keep the handbook's working state, find it again, and spend their effort only on each new question. SGLang finds it through a radix tree and offers a cache-aware order; vLLM finds it through chained block hashes. The handbook is processed once either way. What decides how fast your assistant feels is how long the shared part is, how long the answers are, whether the handbook is still in memory when the next question comes, and who has to wait while others go first.
Research notes: the paper's scheduling algorithm, and a few details
- Multi-GPU. With tensor parallelism each GPU holds a shard of every KV tensor, and the tree is the same on every GPU, so no extra synchronisation is needed (paper, Section 3). For data parallelism the paper describes a router holding a meta-tree of the workers' trees (Appendix A.4); the v0.4 cache-aware router above follows the same idea with an approximate tree per worker.
- Images. For multimodal models, SGLang hashes each input image and uses the hash as the radix key for the image tokens, so the same image is reused (paper, Section 6.2). vLLM puts the image hash into the block's extra hash.
- API models. The paper's Section 5, "API speculative execution", is about black-box API models and does not apply to self-hosted serving, so it is left out here.
- Source pins. SGLang
b2cb24995d4adefb2628d73cbf9cf84dae896bc1and vLLMc23ca06b6d944579ad9d220297441236755b4744, both 8 October 2026; the paper PDF is arXiv 2312.07104v2. Hashes are inresults/sources.json.
References
Papers
- L. Zheng et al. SGLang: Efficient Execution of Structured Language Model Programs. arXiv 2312.07104, version 2.
- W. Kwon et al. Efficient Memory Management for Large Language Model Serving with PagedAttention. SOSP 2023.
Engineering blogs
- SGLang team. Fast and Expressive LLM Inference with RadixAttention and SGLang. LMSYS blog, January 2024.
- L. Yin, Y. Sheng, L. Zheng. Fast JSON Decoding for Local LLMs with Compressed Finite State Machine. LMSYS blog, February 2024.
- SGLang team. SGLang v0.4: Zero-Overhead Batch Scheduler, Cache-Aware Load Balancer, Faster Structured Outputs. LMSYS blog, December 2024.
Documentation
- vLLM. Design: Automatic Prefix Caching, Automatic Prefix Caching, Structured Outputs.
- SGLang. Radix Cache Eviction Policies, Hyperparameter Tuning, Structured Outputs, HiCache design.
- Model configurations: Qwen2.5-0.5B, Qwen2.5-7B-Instruct.
Source code checked (8 October 2026)
- SGLang
b2cb249: schedule policy flag, eviction policy flag, LPM fallback, radix cache, jump-forward hook. - vLLM
c23ca06: cache config, scheduler config, async scheduling default, last-token rule.
Companion results